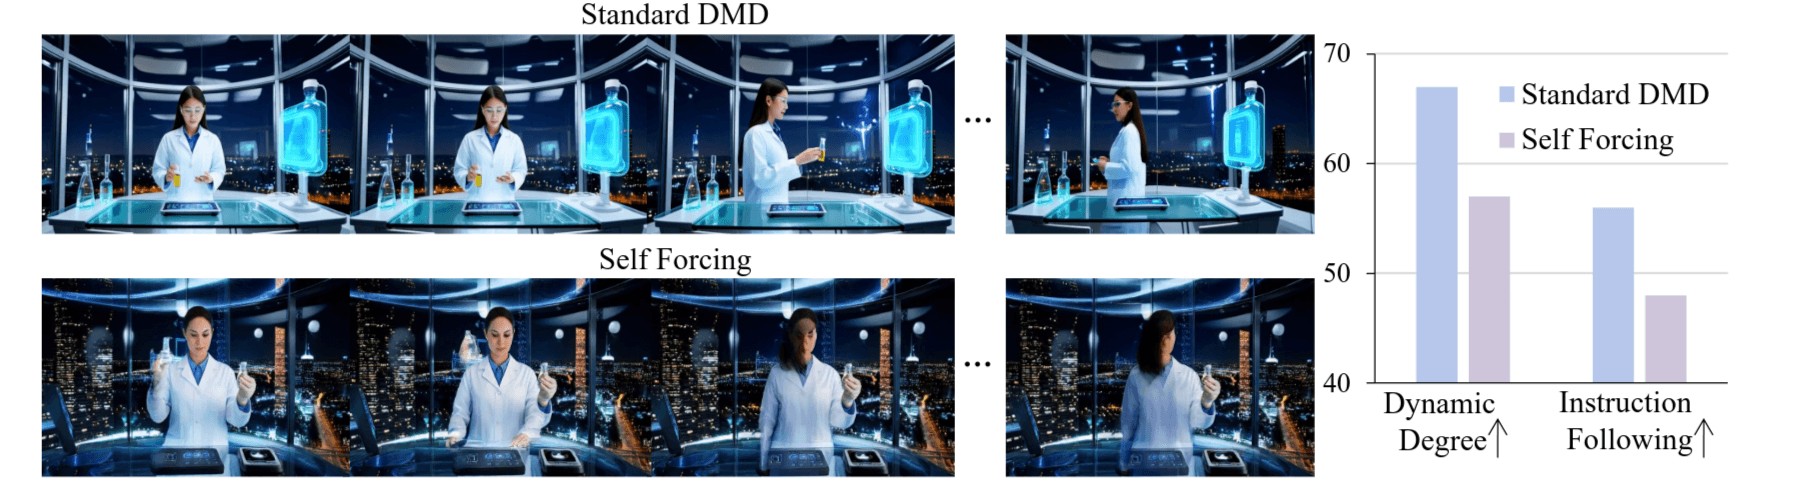
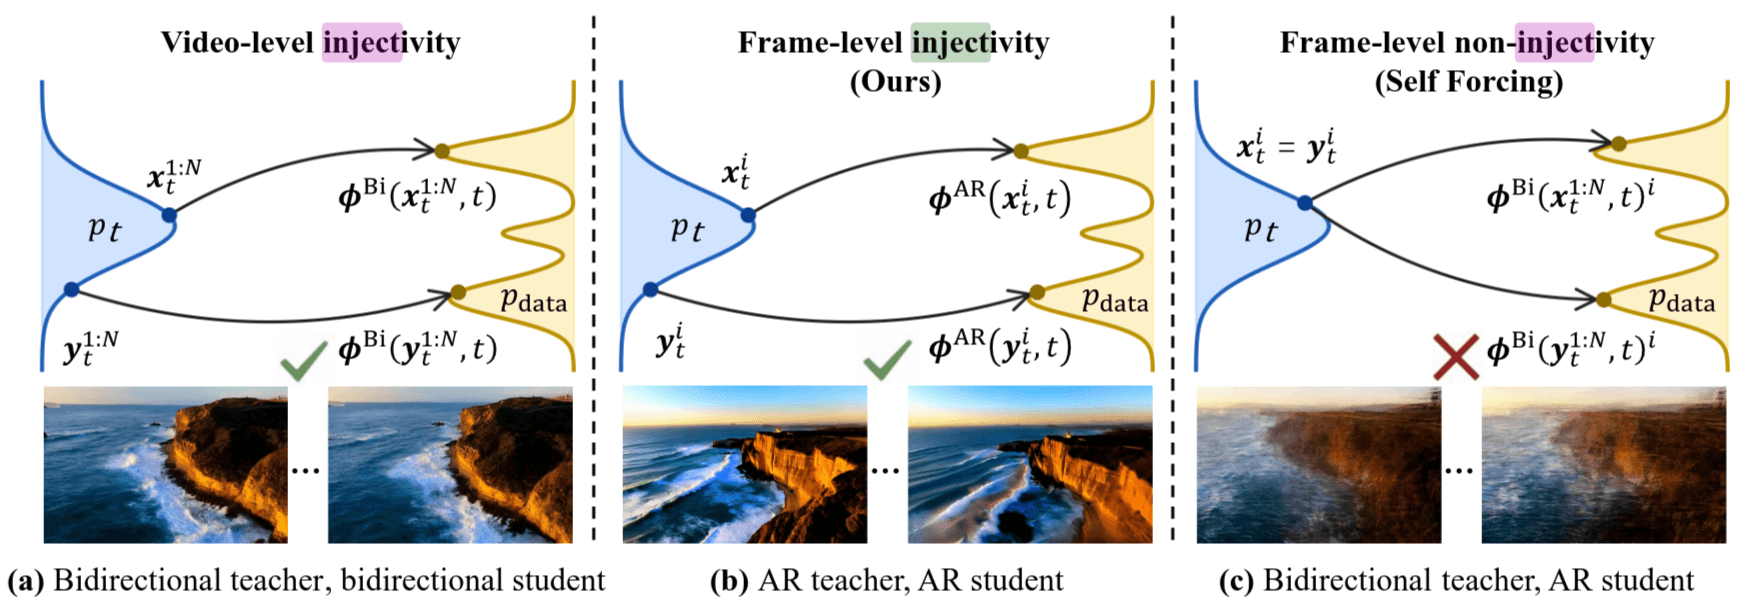
Causal Forcing: Autoregressive Diffusion Distillation Done Right for High-Quality Real-Time Interactive Video Generation
causal forcing, 使用AR Teacher进行ODE初始化.
Loading...
AnimateDiff: Animate Your Personalized Text-to-Image Diffusion Models without Specific Tuning
讲背景: stable diffuison, DreamBooth, LoRA的发展, T2I任务成本降低, 但是将motion dynamics添加到T2I模型做animation并不容易. 提出AnimateDiff, animation personalized通用框架, 可插拔模块.(这个摘要云里雾里的, 什么叫animate personalized, 还是有必要解释一下的. 根据已有知识, 它的贡献应该是为为T2I任务引入了时间层, 支持视频生成, 即原文提到的motion dynamics.)
CogVideoX: Text-to-Video Diffusion Models with An Expert Transformer
text-to-video的基础模型, 能生成10秒的长视频, fps为16, 分辨率768x1360. 卖点是长视频和文本连贯性. 3D-VAE, expert transformer, 分阶段多分辨率训练, effective pipeline. 结果在生成质量和予以对齐上都有所改进.