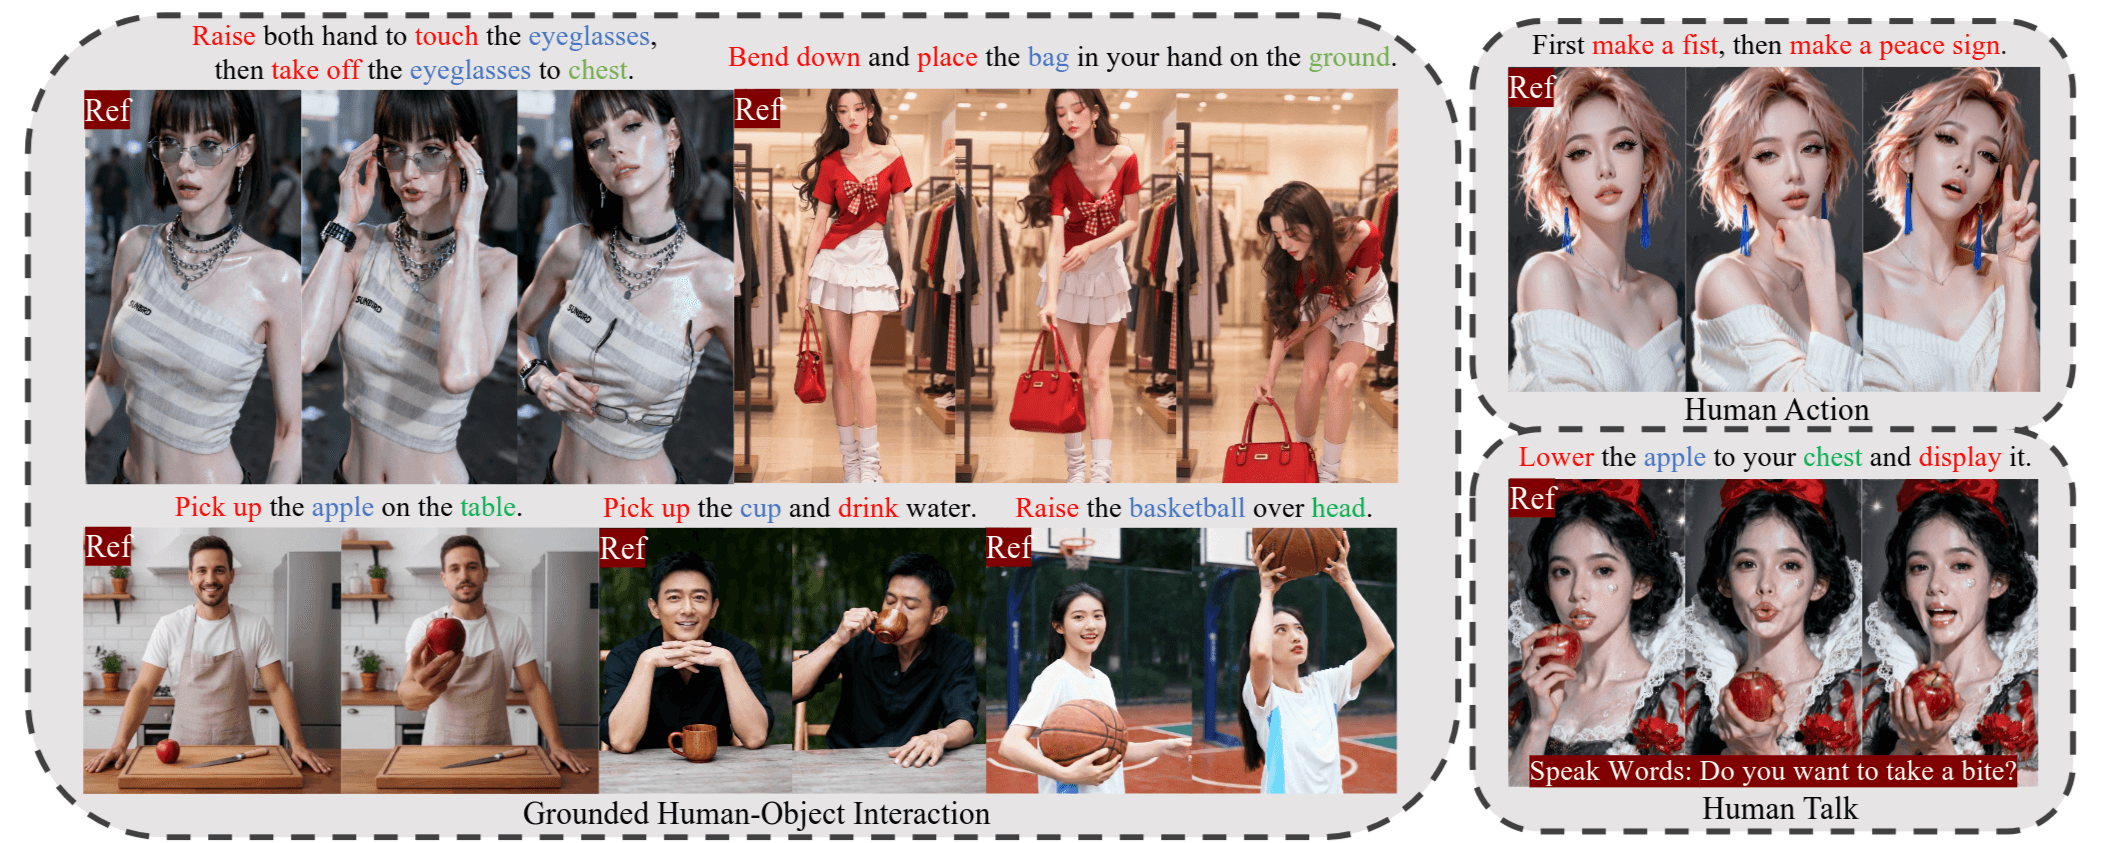
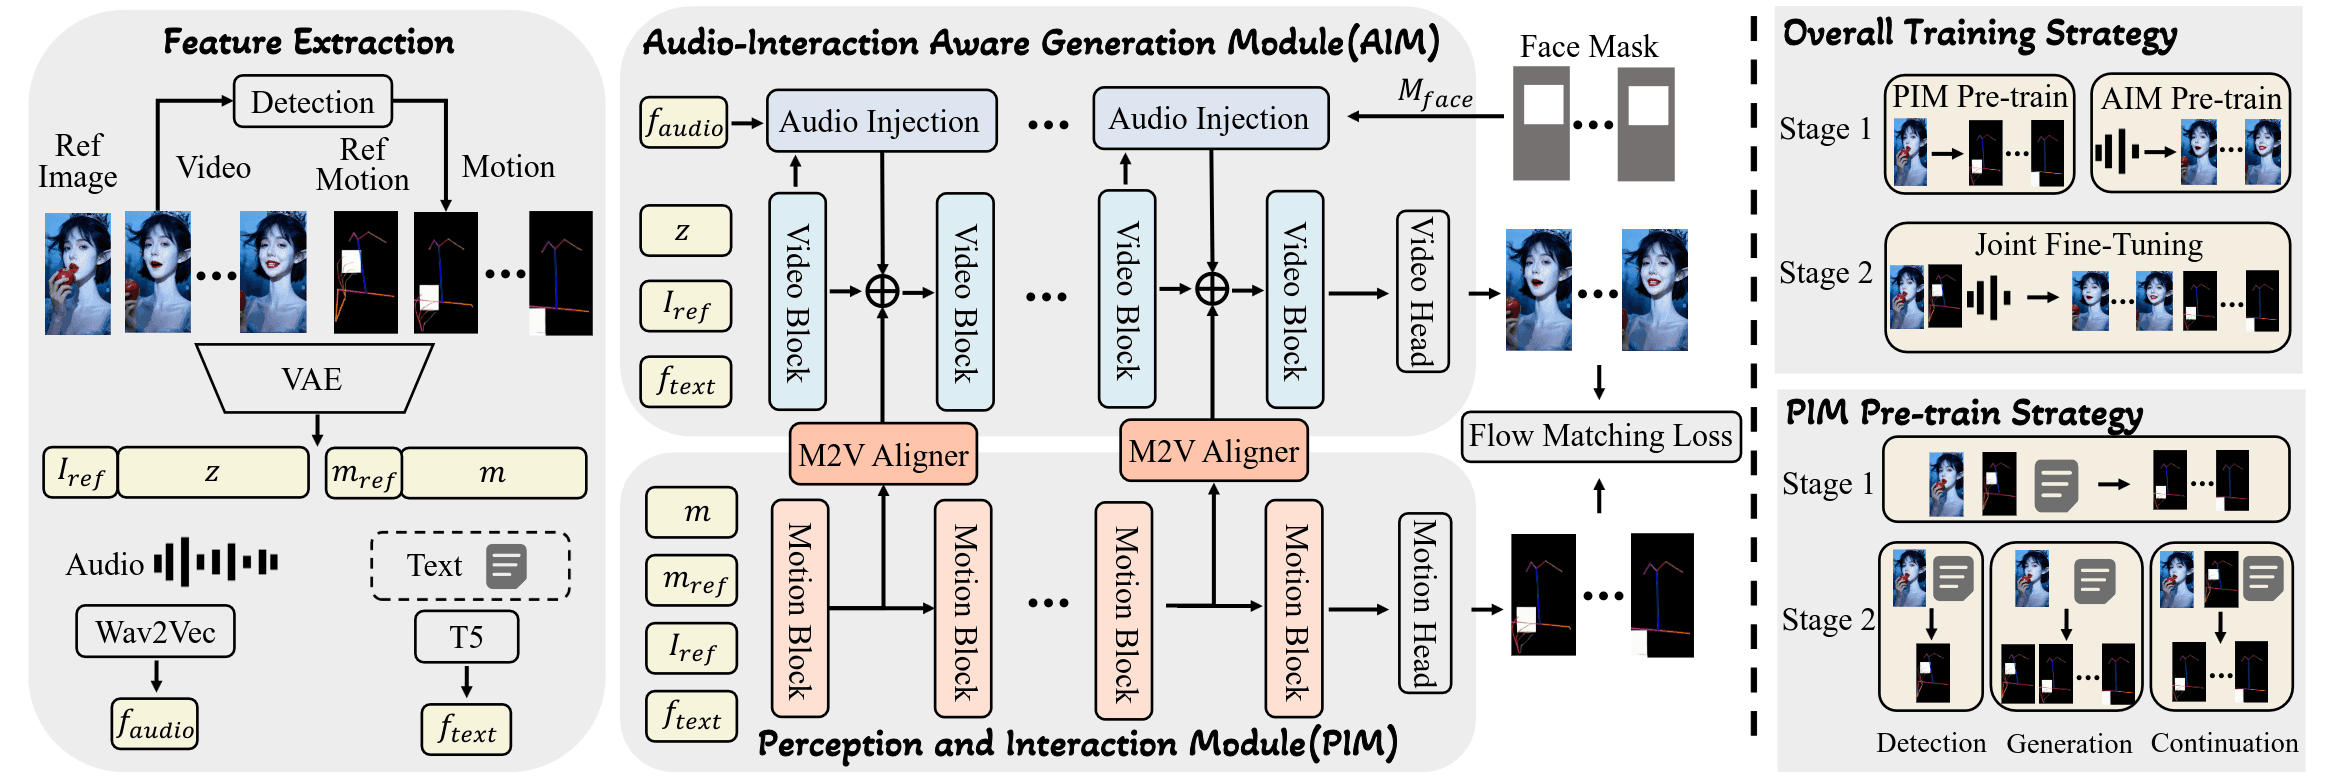
Making Avatars Interact: Towards Text-Driven Human-Object Interaction for Controllable Talking Avatars
现有方法可以完成简单的人体动作控制, 但是扩展到Human-Object Interaction仍是开放的挑战. 方法, benchmark
Loading...
EchoMotion: Unified Human Video and Motion Generation via Dual-Modality Diffusion Transformer
现在是视频生成模型追求外观的保真度但是牺牲了基础的运动学原理学习, 无法生成人体复杂的动作. EchoMotion: 1)拓展了DiT到双分支结构支持不同的模态; 2) MVS-RoPE; 3) Motion-Video Two-Stage Training Strategy. 还提了个数据集HuMoVe, 80,000个视频-动作对
Conditional Image-to-Video Generation with Latent Flow Diffusion Models
讲任务: cI2V旨在从一张图片和一个条件生成满意的视频. 讲挑战: 同时生成空间外观和时间动态. 讲方法: 提出Latent Flow Diffusion Model(LFDM), 基于条件生成一个optical flow序列, 用这个optical flow扭曲图片. 训练分为两个阶段: 1) 无监督学习, 图片对的训练, 训练一个latent flow的自动编码器; 2) 条件学习阶段, 使用3D-UNet-based Diffusion预测时间latent flow. 讲优势: 之前的条件生成要同时关注时间和空间维度, 它这种方法只需要关注时间维度.